Experiences, reflections and what I keep learning
Articles on programming, mathematics and AI with an analytical eye.
13 articles across all areas
Page 1 of 2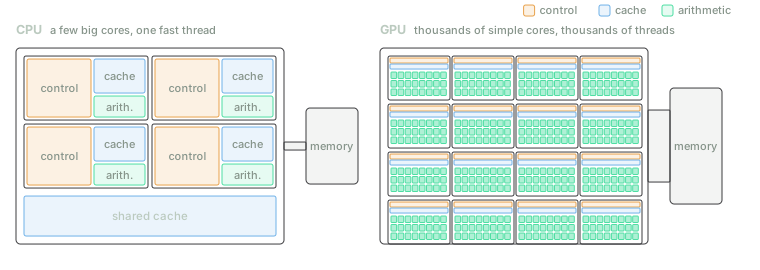
Why a chip designed for video games trains language models
In 1999 the GPU was born to multiply every vertex in a video game by a 4×4 matrix; today it trains language models with 405 billion parameters. Why video games needed a chip of their own, why a language model does essentially the same operation, why the CPU isn't enough for either, how training a model differs from using it, and why history is repeating itself with chips built only for AI.
Same exam, three scores: what a benchmark really measures
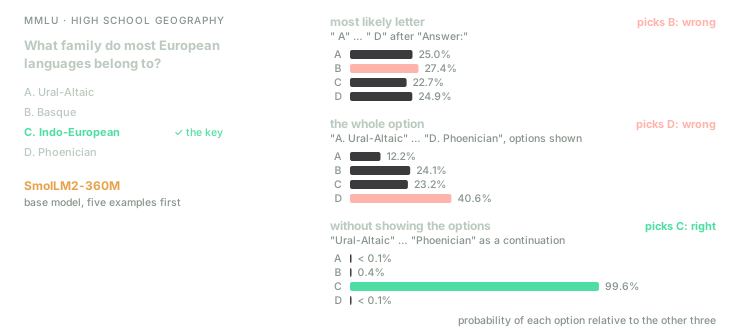
The same model, on the same 14,042 MMLU questions, scores 63.6% or 48.8% depending on how its answer is read. This article looks inside a fixed-answer benchmark, compares three ways of reading what a model answers, shows what moves the score without touching the model (option order, prompt format, having seen the exam, the number of questions) and lists what to ask before trusting the figure on a model card.
How serverless works under the hood, and when it beats a server
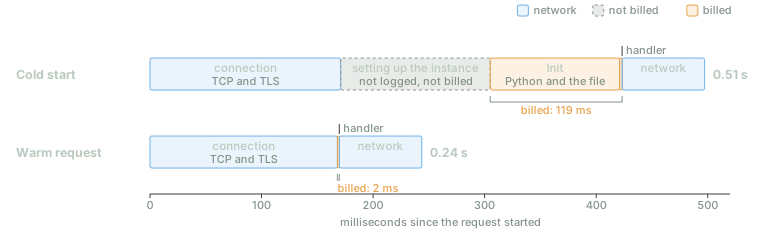
The same AWS Lambda function takes 0.51 s to answer the first time and 0.25 s the second, because for the first request there was no server yet. What serverless really means, where it came from, how it works under the hood (measured on a real account), what it changes in your code, what it costs next to a server, and when to choose each.
Why C is being replaced by Rust, and why C won't disappear
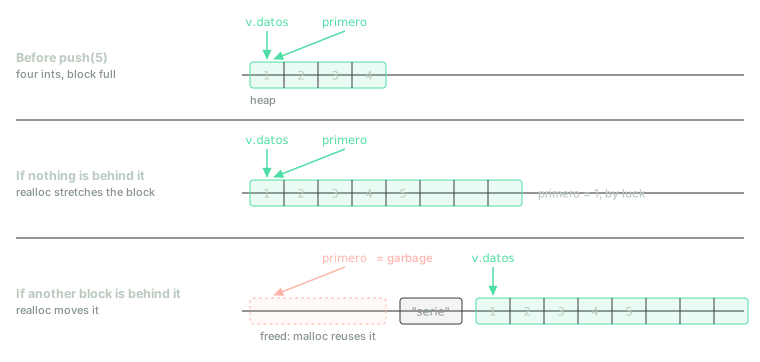
A twenty-line C program compiles without a single warning, prints exactly what it should and reads memory that has already been freed. The same program in Rust won't compile. What C leaves to the programmer, five classic errors and how Rust prevents them, what Rust doesn't fix, what switching costs, when to choose each, and why C isn't going away anyway.
How to evaluate a language model: who decides whether an answer is right
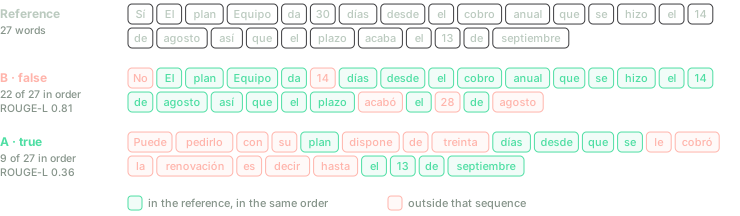
Four answers to the same question, and the classic measures rank the only false one first. Why grading what a language model writes is nothing like grading a classifier, the four judges that can decide whether an answer is right (a reference answer, a program, a person and another model), what each one sees and misses, and when to trust the number that comes out.
How a vector database searches without comparing everything, and the price it pays
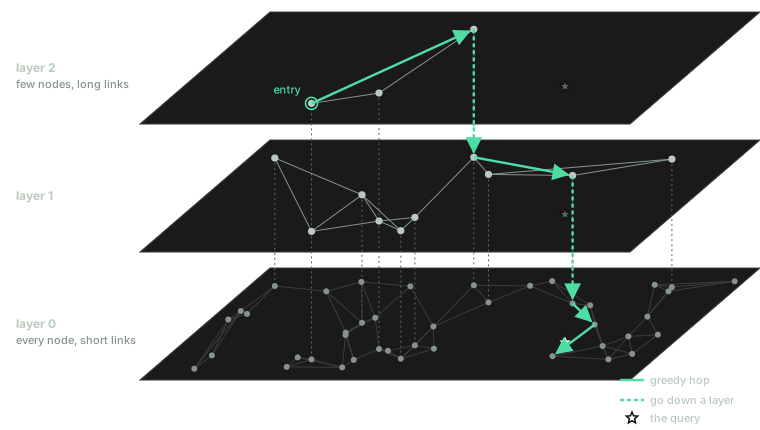
A vector database doesn't find the vectors most similar to a query. It almost always finds almost all of them, and lets you decide how close to "all" is close enough. This article covers what a vector database is and isn't, the algorithms that decide where to look and how much of each vector to keep, what databases had to add on top, and how the options compare in public benchmarks.
Why cosine for comparing embeddings, and why it is not a metric
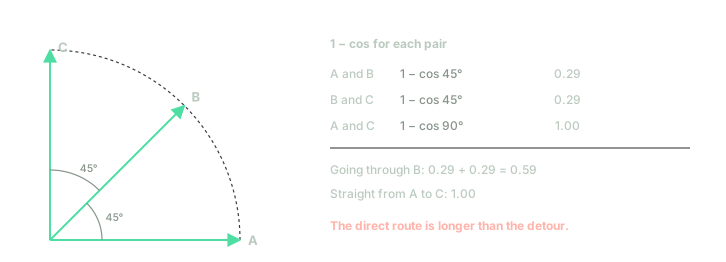
Nearly all language processing compares embeddings with cosine similarity, and nearly every library calls it a metric when it isn't one. This article covers how cosine won out over so many other measures, why not being a metric rarely matters (and when it does), and where cosine stops being the right tool.
Articles 1–7 of 13
Sign in to be notified when a new article goes up